
Foundations of Machine Learning
This course will cover foundation of ML and will be focusing on mathematical aspects in Machine Learning
Pods in this Course
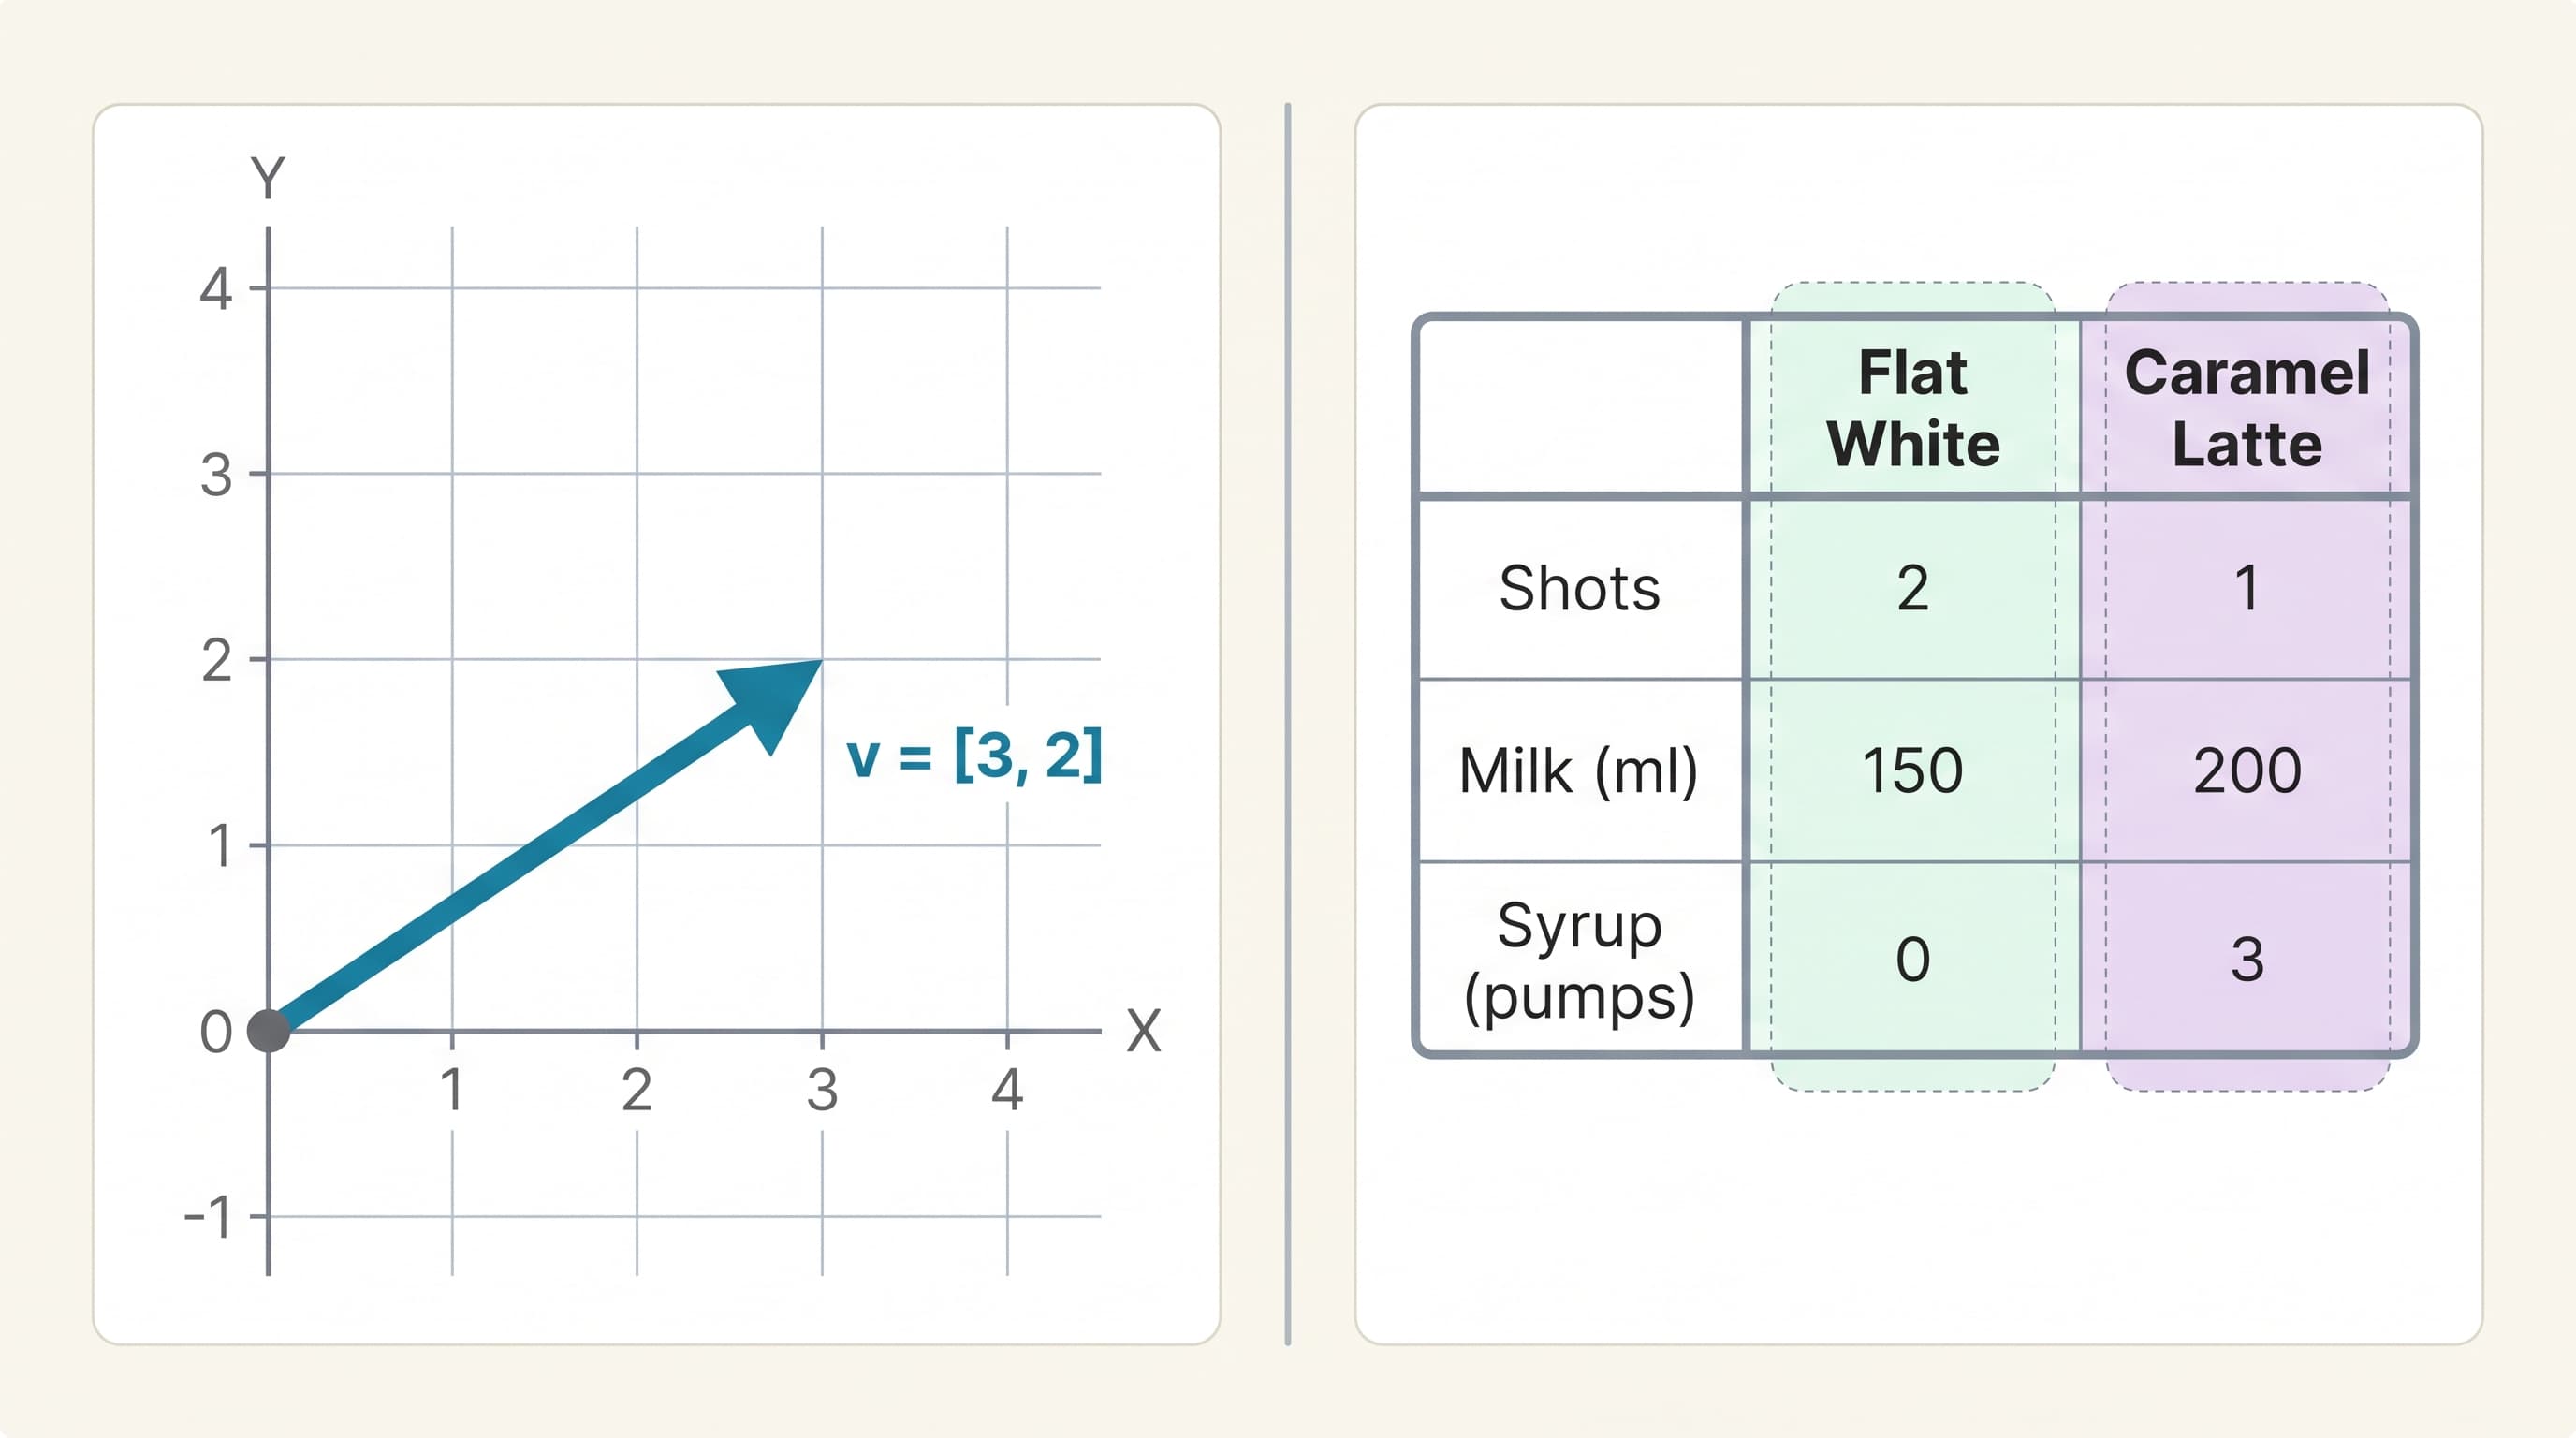
Vector, Basis and Linear Transformation
What are vectors and how we can represent entities in form vecotr and matrix and span, baiss, linear transformation
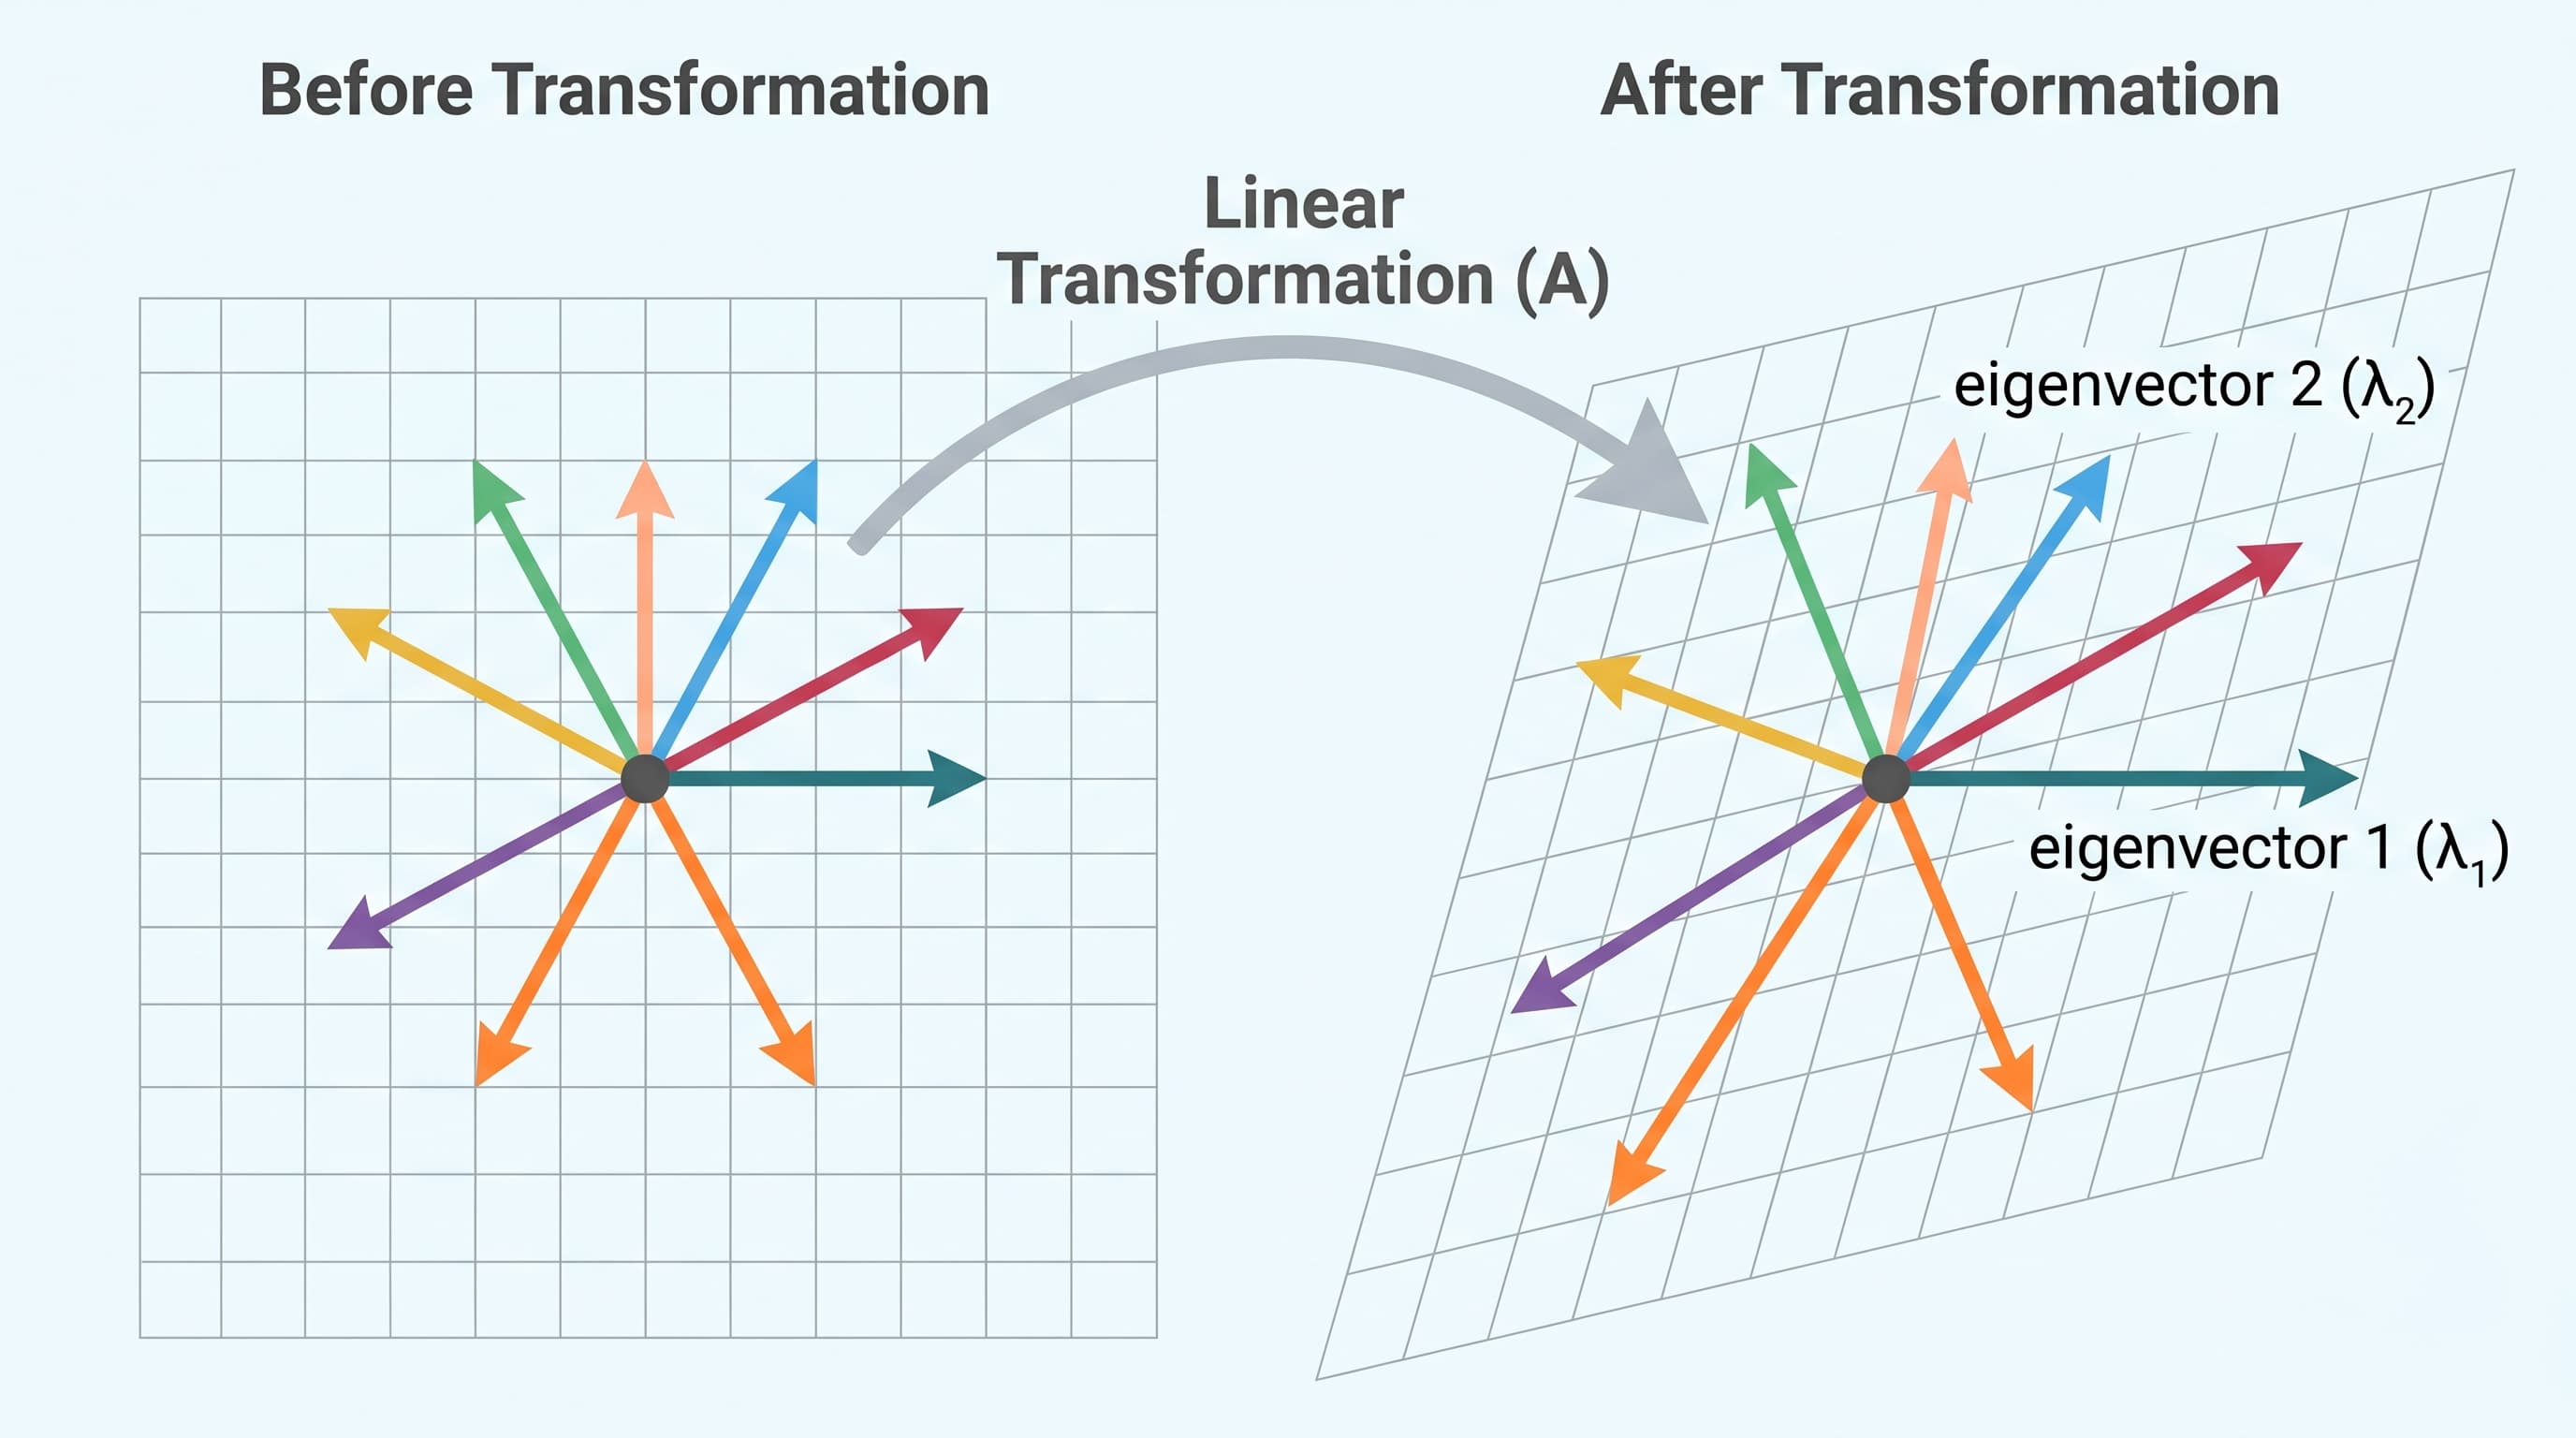
Importance Eigen Values and Eigen Vectors in Machine Learning
Importance Eigen Values and Eigen Vectors in Machine Learning
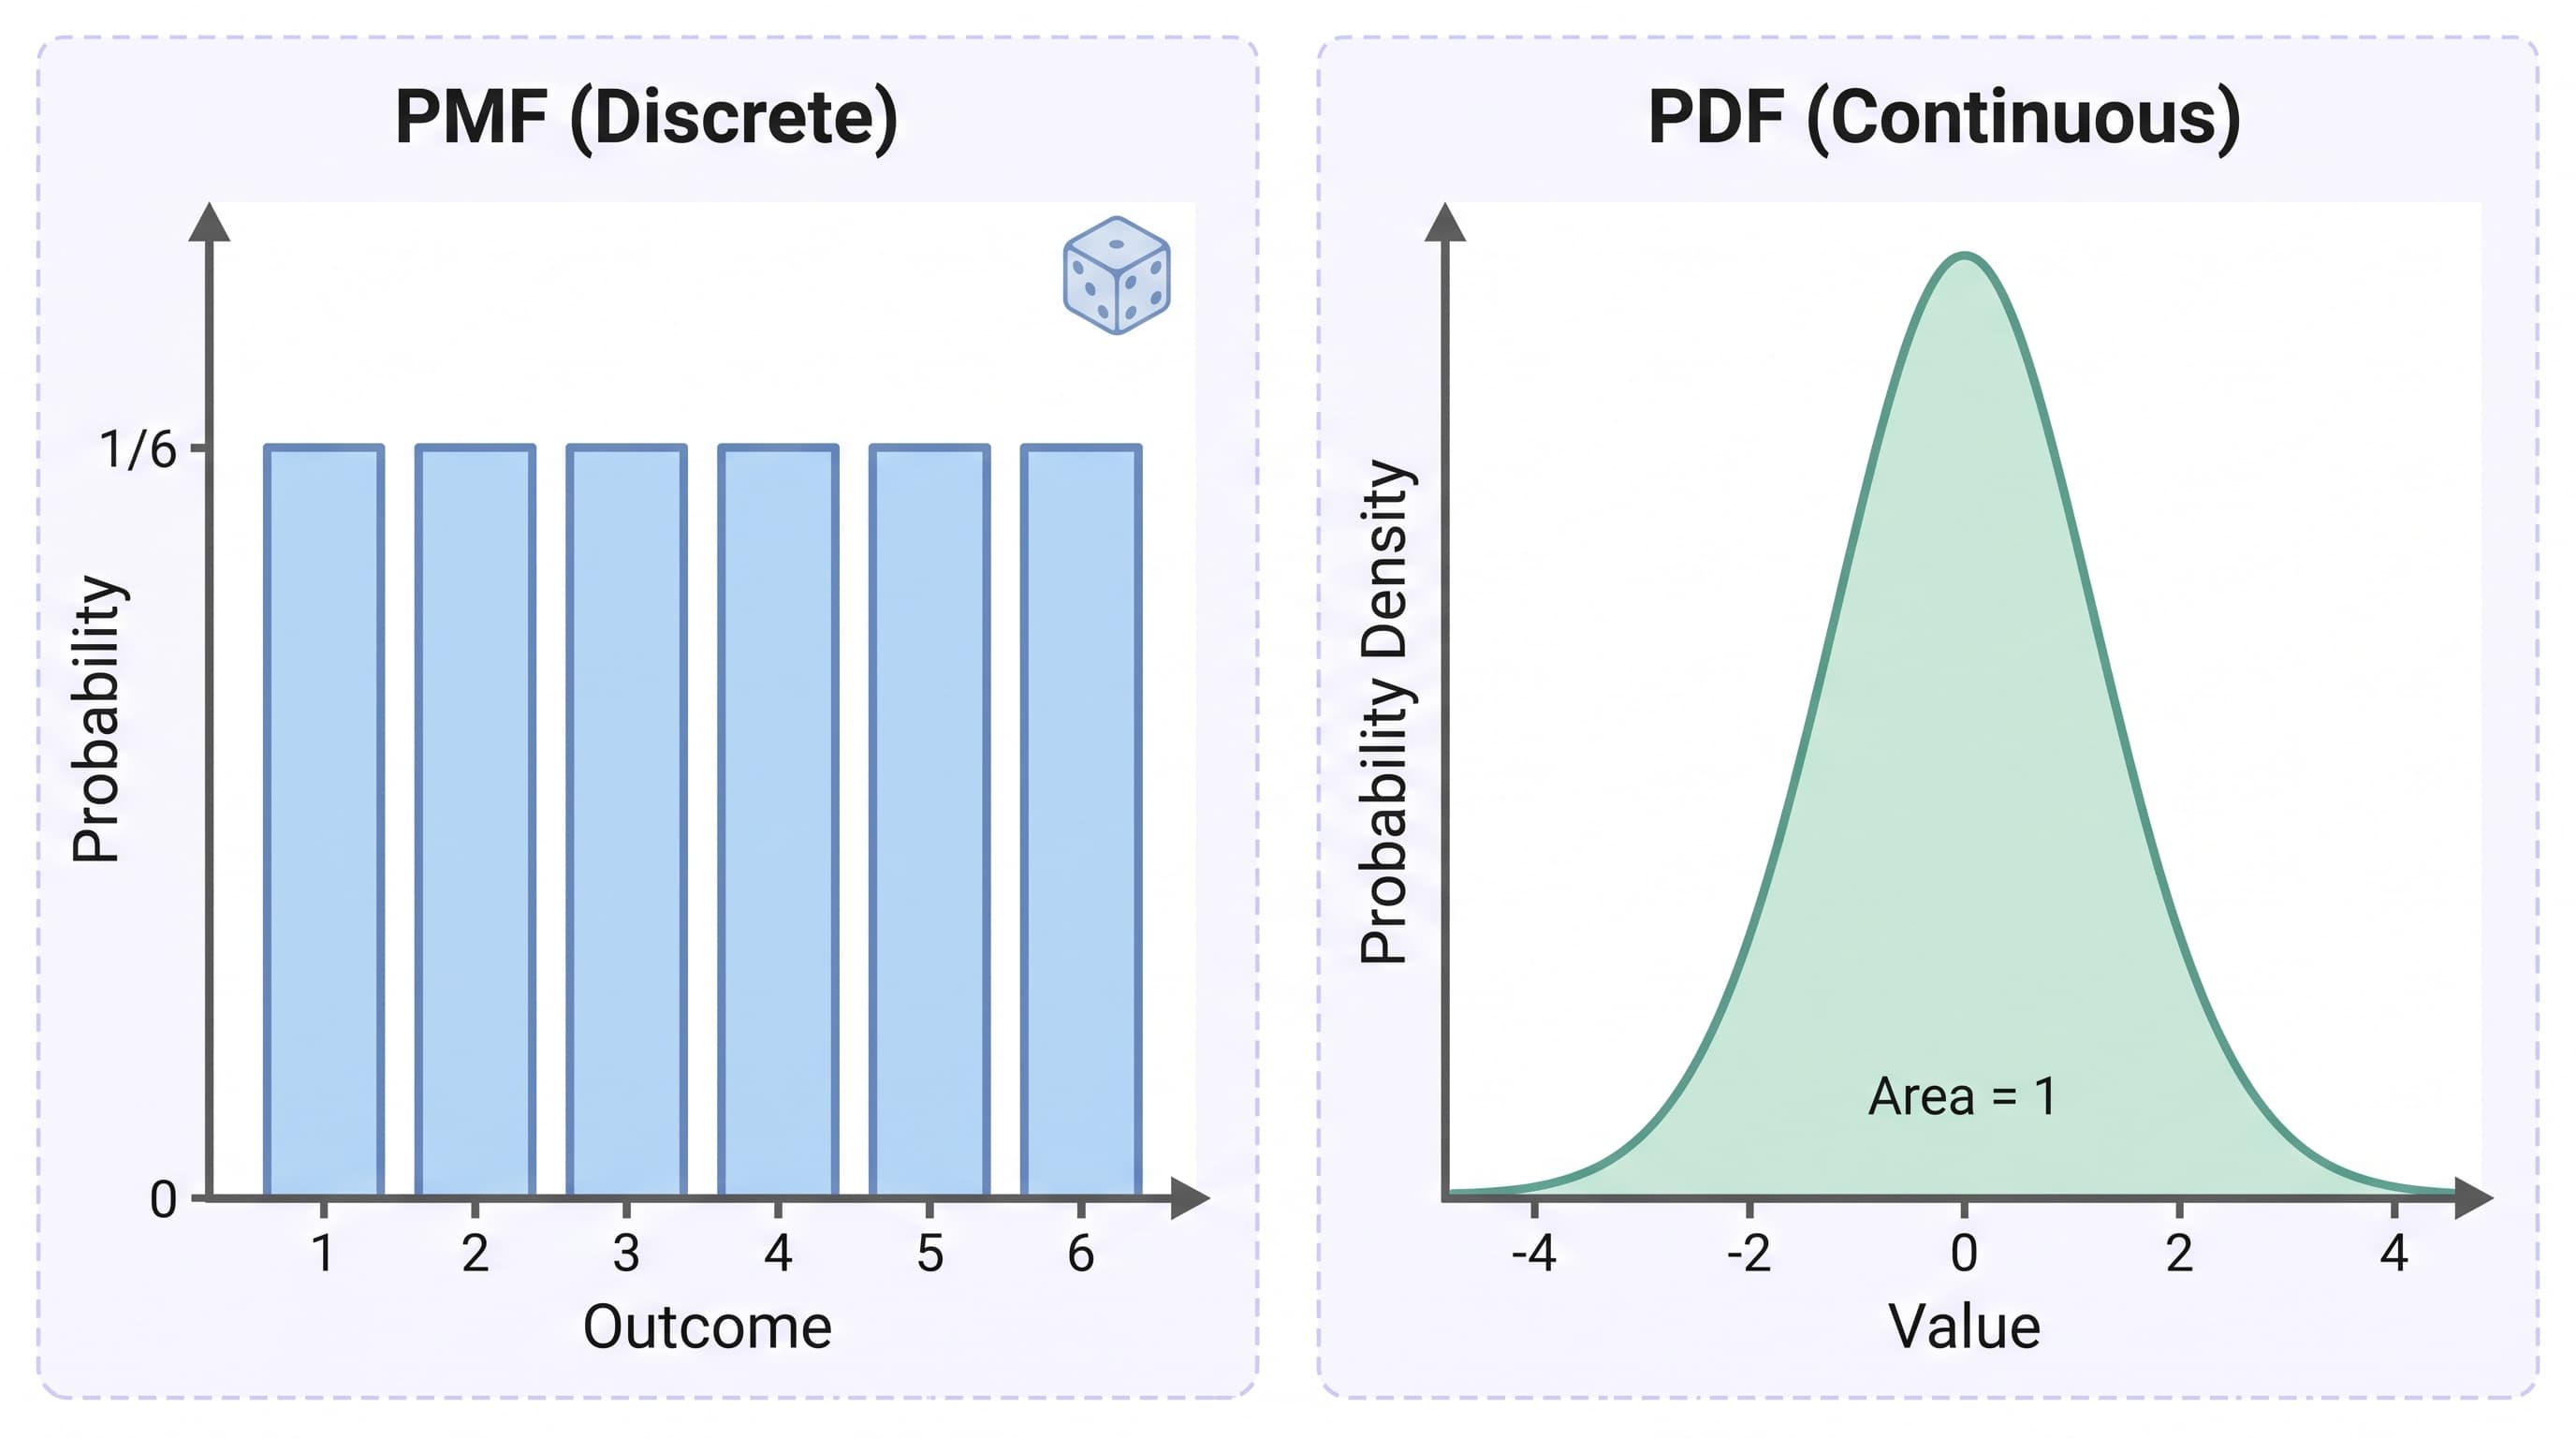
Probability Distribution in Machine Learning
Probability Distribution in Machine Learning
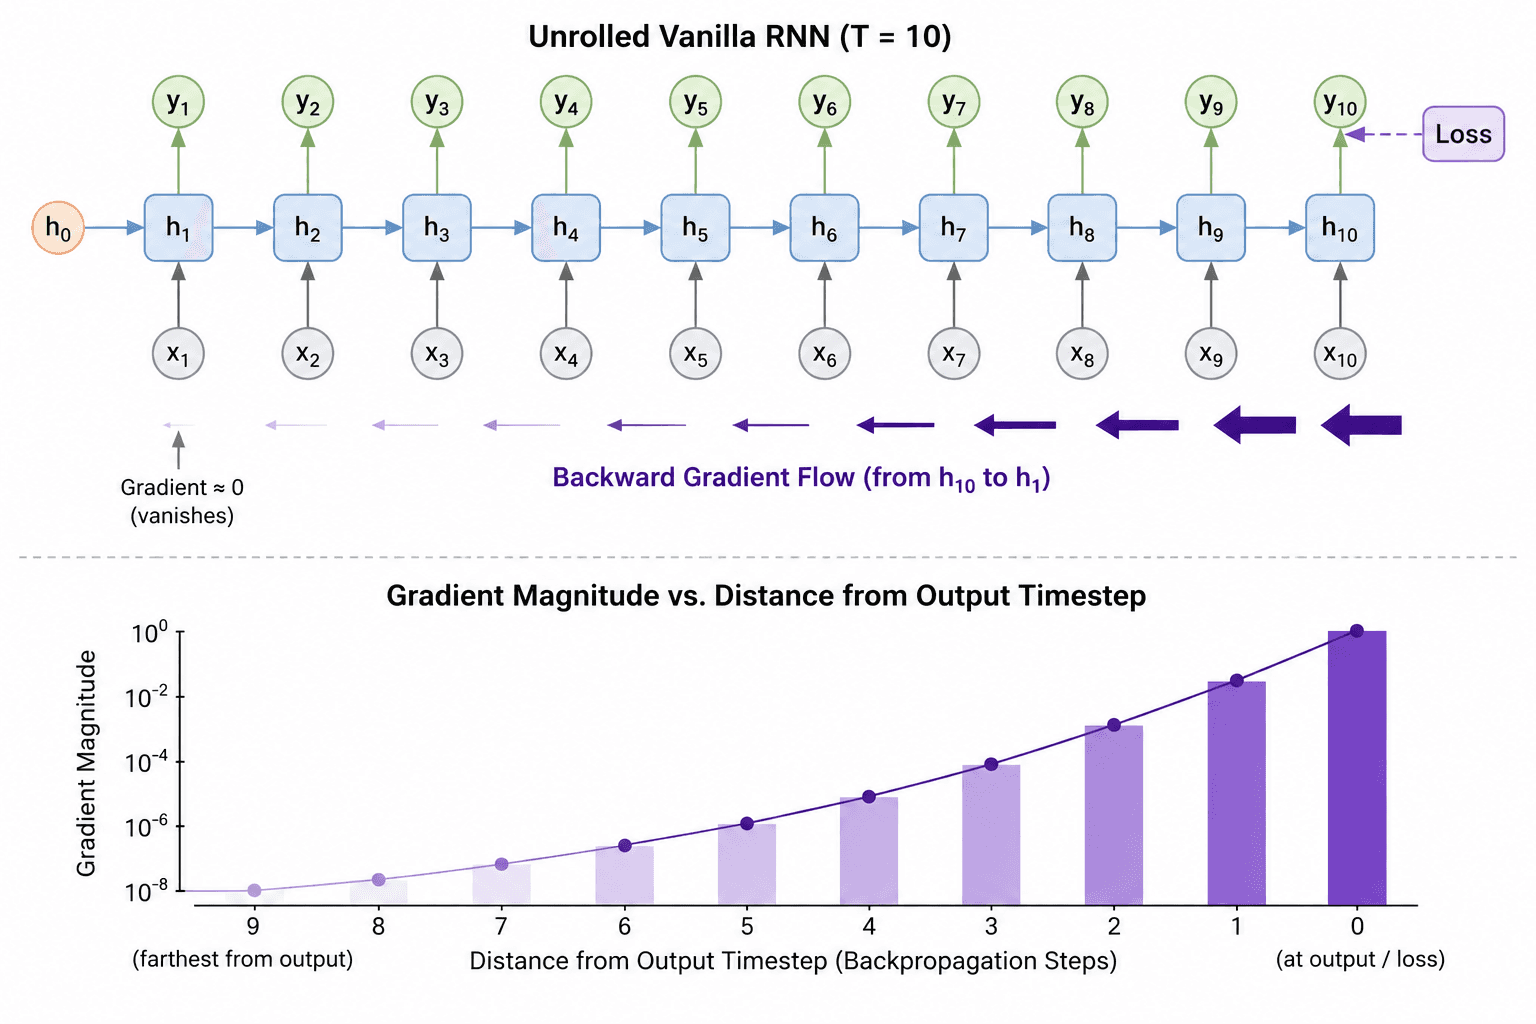
All About LSTM
All About LSTM
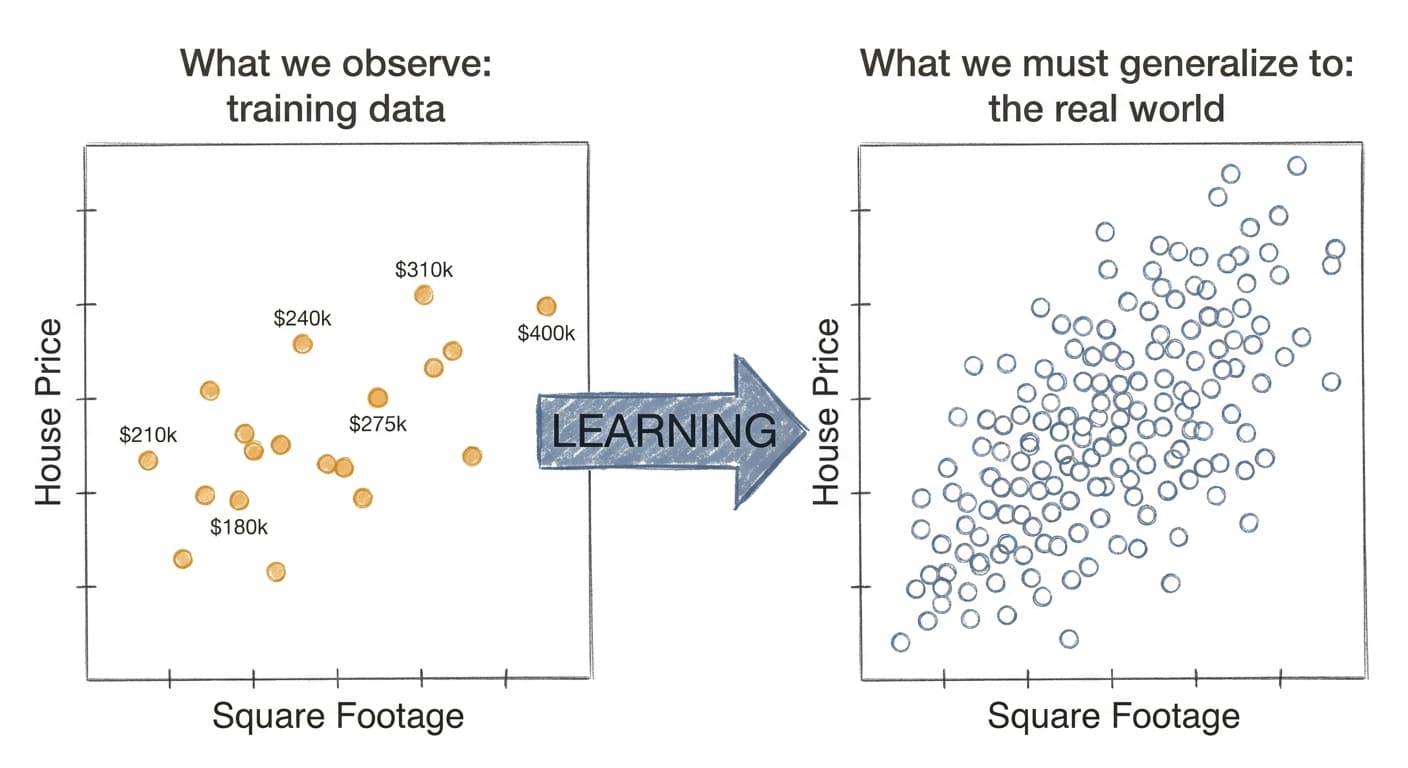
Statistics in Machine Learning
Statistics in Machine Learning
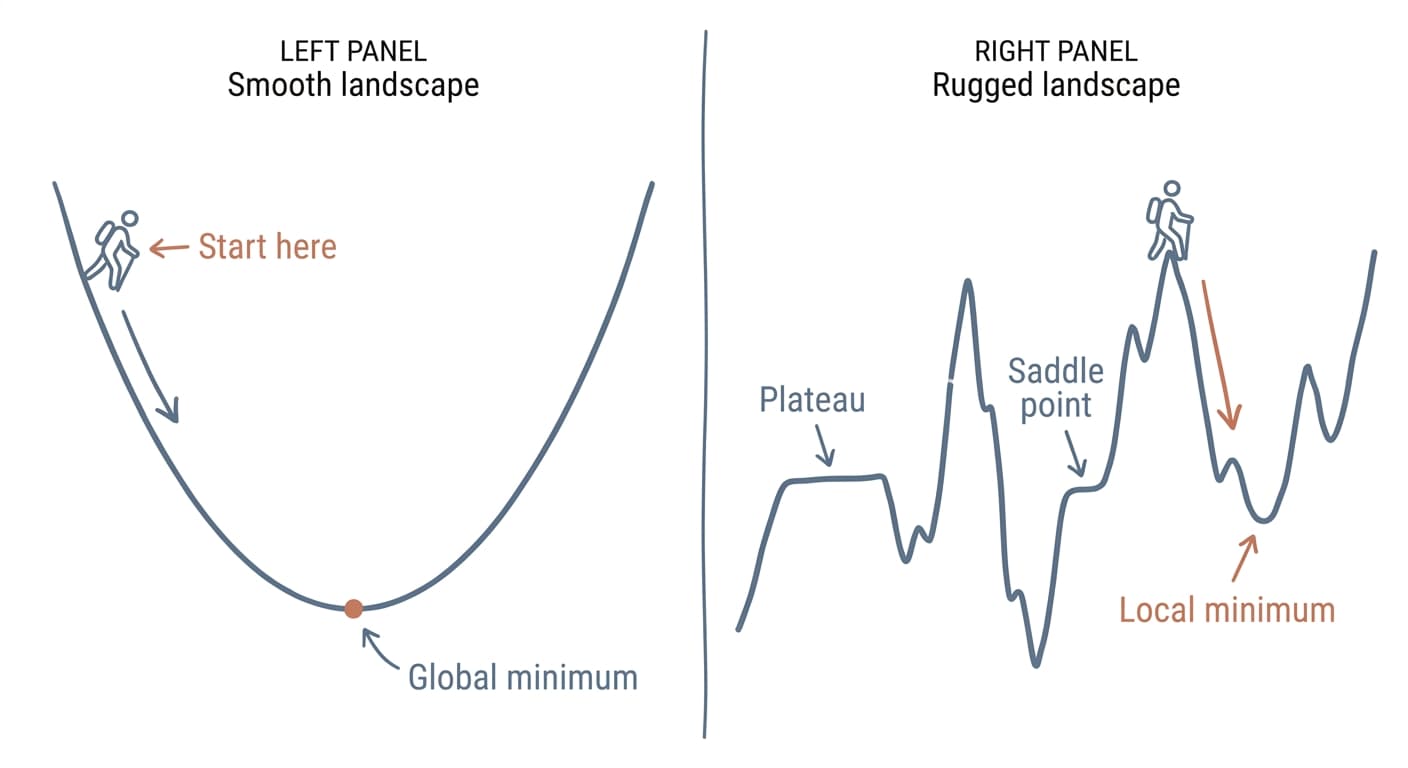
Gradient Descent and Why Learning Rates Misbehave
Gradient Descent and Why Learning Rates Misbehave
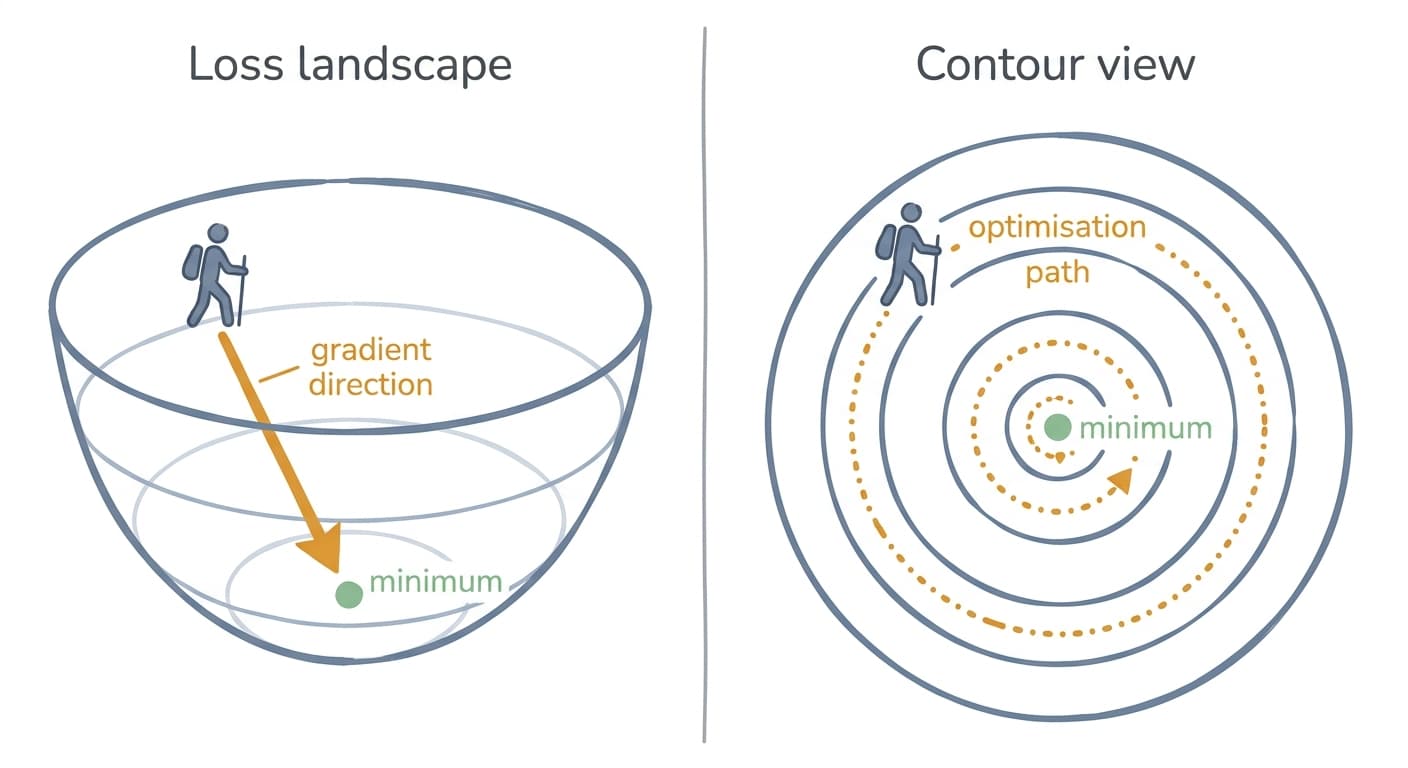
Backpropagation from Scratch: Computing Every Gradient by Hand
Backpropagation from Scratch: Computing Every Gradient by Hand
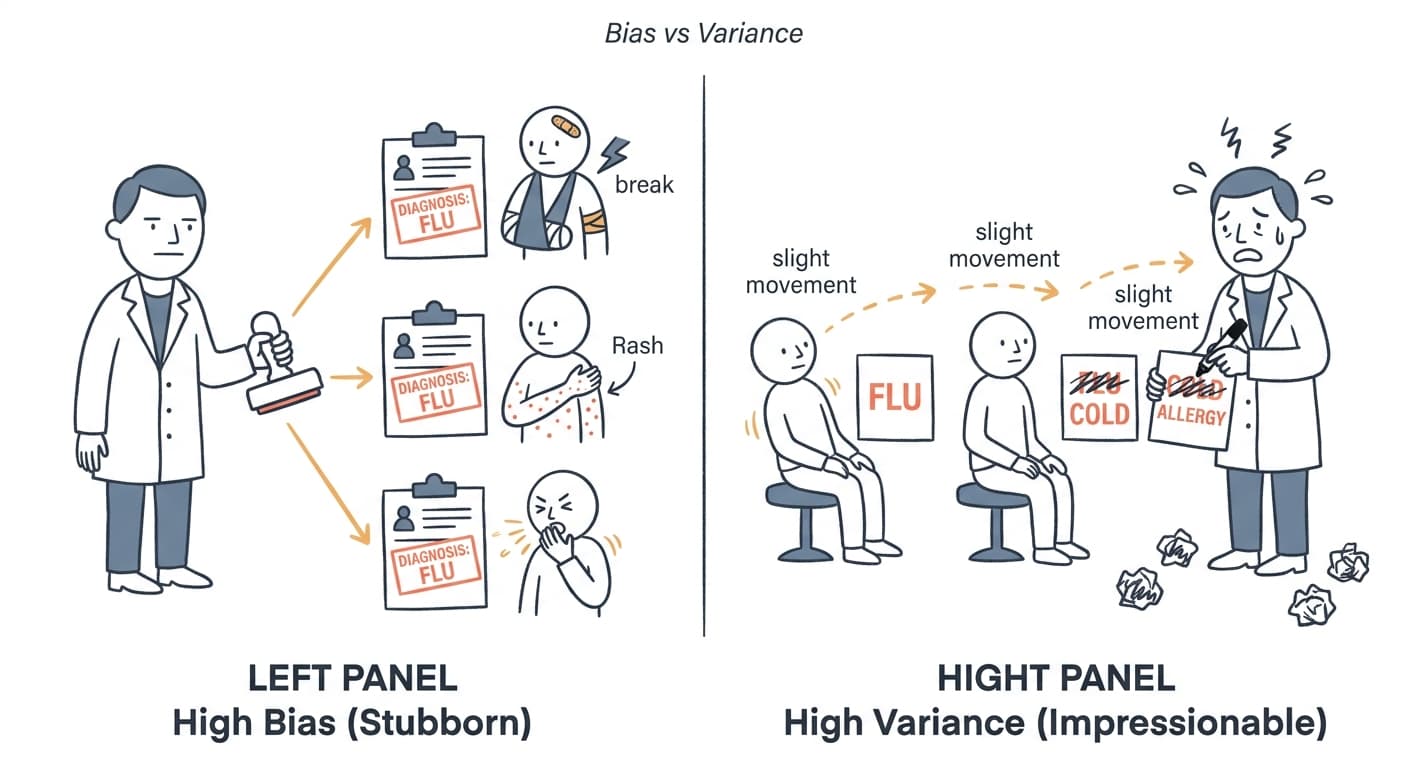
The Bias-Variance Tradeoff, Diagnosed on Real Data
The Bias-Variance Tradeoff, Diagnosed on Real Data
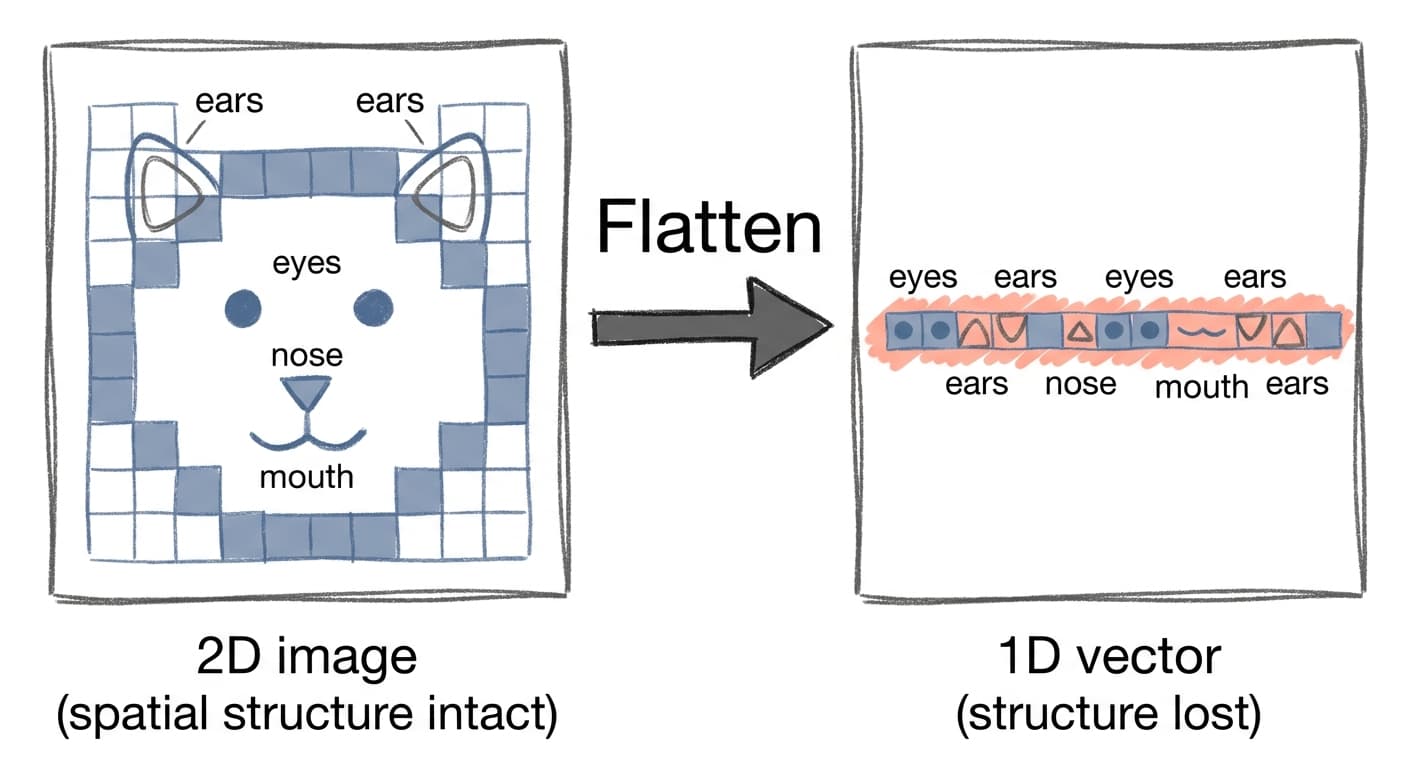
Convolution from Scratch: How a CNN Actually Sees an Image
Convolution from Scratch: How a CNN Actually Sees an Image
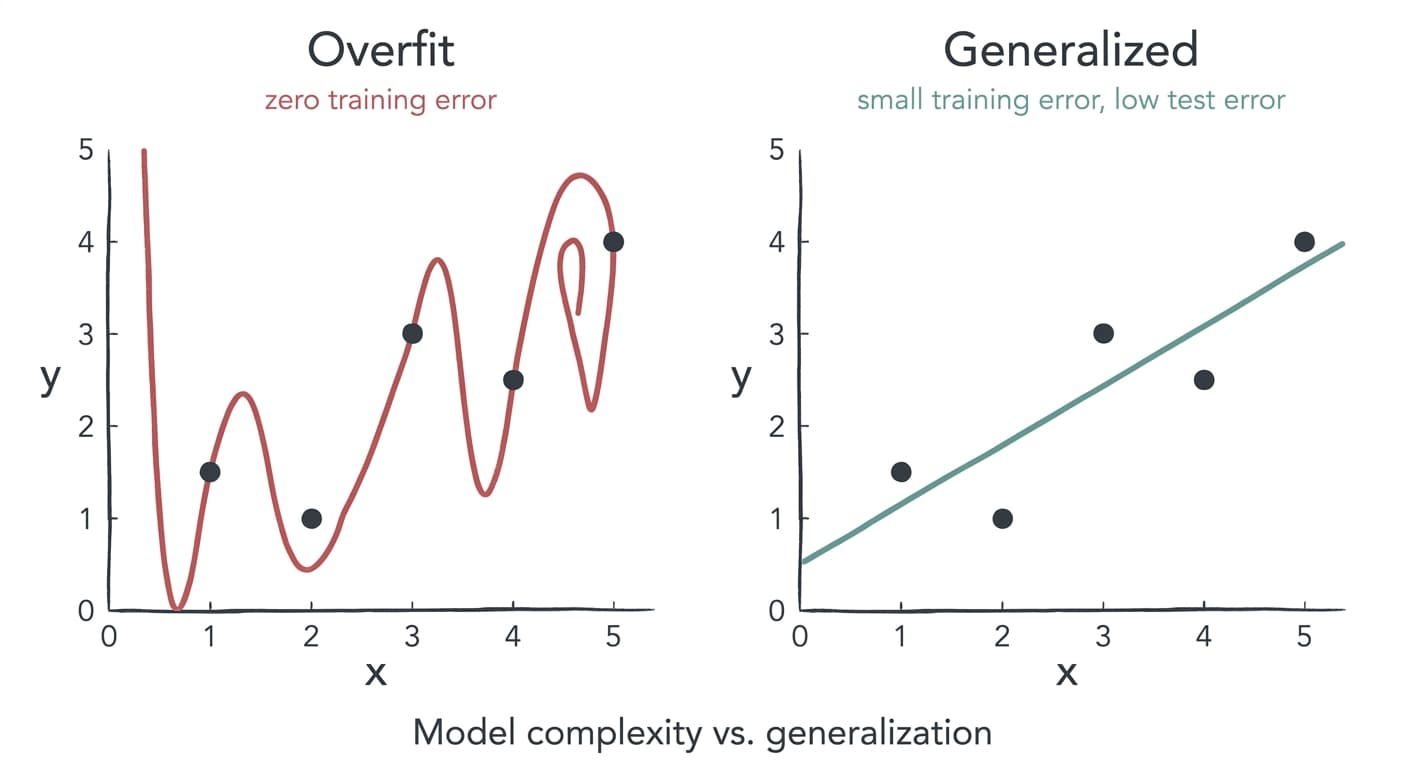
Regularization from Scratch: L2, L1 and Dropout — How to Cure an Overfit Model
Regularization from Scratch: L2, L1 and Dropout — How to Cure an Overfit Model
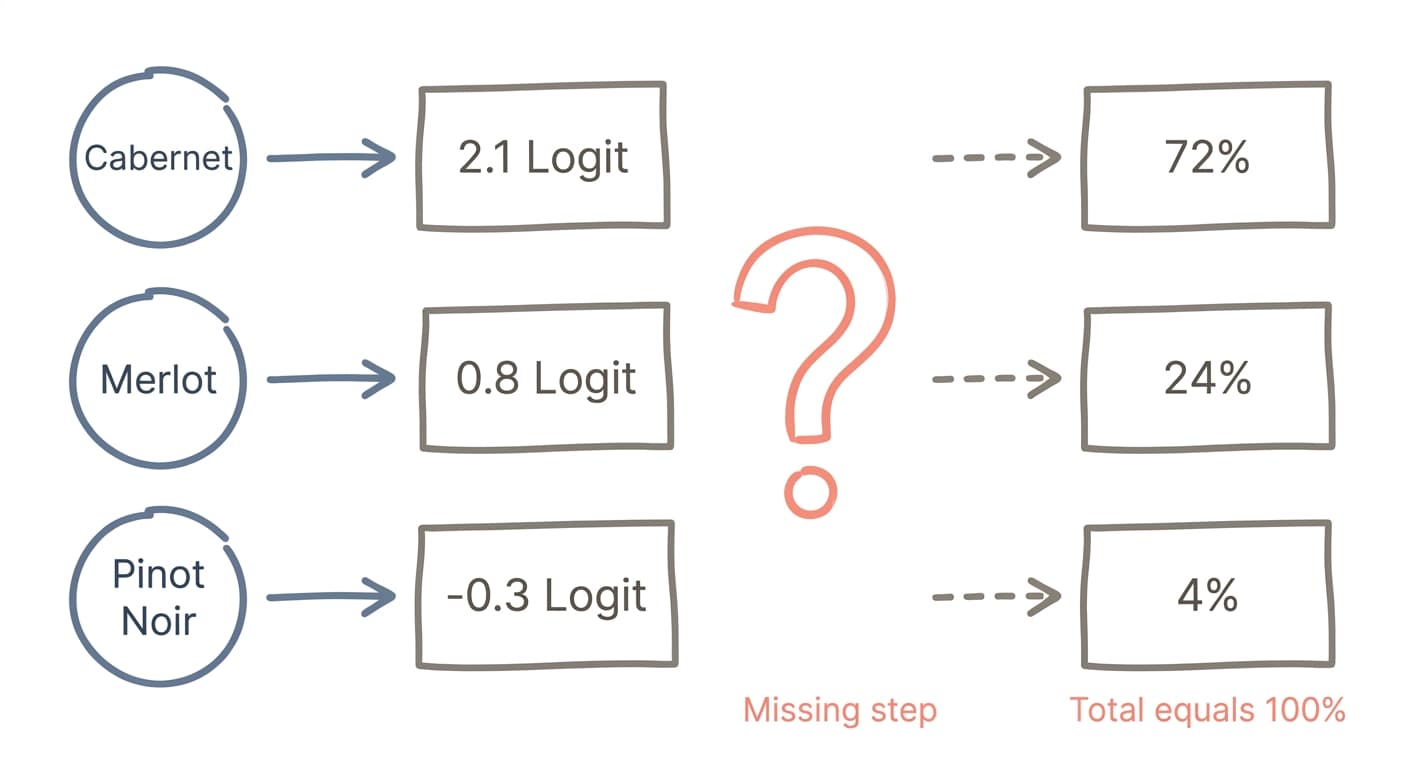
Softmax and Cross-Entropy from Scratch: Why the Gradient Is Just Prediction minus Truth
Softmax and Cross-Entropy from Scratch: Why the Gradient Is Just Prediction minus Truth